In our recent guide on choosing the best open-source LMS for universities, governments, and enterprises, we explored why open technologies provide public institutions with greater control, transparency, and long-term value compared to proprietary platforms. This article takes that discussion a step further.
Government organizations worldwide are steadily expanding their online learning initiatives, ranging from internal training to national digital education programs and public universities. This expansion brings a distinct set of needs: robust security, strong data protections, long-term sovereignty, and the ability to scale beyond typical platforms limits.
Below, we outline the key requirements of secure LMS solutions for governments, and how modern, extensible software can meet them today.
Over the past few decades, data has become one of the most valuable, and often misused, resources. It is used to analyze behavior, track individuals or groups, and is frequently handled in ways that range from careless to unethical. For government agencies adopting commercial software, this creates a persistent risk of data leakage.
If your citizens’ information is hosted in a country with unfriendly or overly relaxed data policies, that data may be accessed by that jurisdiction without your knowledge, and in many cases, providers are legally prohibited from notifying you.
A second equally serious concern is data can be held hostage. If a provider changes its pricing, terms, or product direction after your LMS is already live, your team may abruptly lose access to the platform and the underlying data. Governments can find themselves pressured into paying far more than planned, with little benefit to the public. Even worse, diplomatic tensions between countries could render your systems inaccessible overnight, with no path to recovery.
For these reasons, data sovereignty is essential. Any government LMS must guarantee data portability and full control over where information is stored. You cannot consider a platform secure if you cannot move your data when needed or if you lack the authority to decide where that data resides.
Government learning systems depend heavily on the ability to inspect, trust, and control the software they use. This makes the choice between closed source, source-available, and open-source software not merely a licensing preference but a fundamental security concern.
Closed source software cannot be audited or edited. This limitation creates a significant problem: without the ability to verify what the code is doing, governments cannot ensure that providers meet security requirements. Backdoors or undisclosed behaviors could exist, and your team would have no reliable means to detect them or have the software independently reviewed. For this reason, closed source software is categorically unacceptable for a secure government system; governments must have access to the source code of the tools they use.
Source-available software provides limited transparency but is still restrictive. While it allows governments to view the code, it often imposes significant limitations on how the software can be run, modified, or distributed. Governments remain tied to a single provider without a straightforward way to exit, and agencies may face legal challenges if they attempt to create their own version of the software after having viewed the source code of a working solution. The company that produced the source-available software may have a copyright claim against any code governments use to replace the software if they need to migrate away from it.
Open-source software is the only model that offers the transparency and control governments require. With open source, you can:
If a provider becomes unresponsive or a hosting location becomes risky, the software can be migrated, redeployed, and maintained by a new team without any disruption. This level of independence makes open source the only sustainable foundation for secure government training programs.
When evaluating an open source LMS, the strength of the community behind the software is crucial.
A platform maintained by a single company offers limited protection: if that company shifts priorities, closes, or becomes unreachable, governments relying on that system are left exposed to disruption.
A healthy open-source community, on the other hand, provides:
Furthermore, communities with multiple providers help newcomers get oriented quickly. Thus, between different providers and community resources, governments can develop in-house expertise that could replace traditional providers if necessary or if organizational goals favor greater independence.
In addition to robust security requirements, government e-learning programs require far greater scale than most private university or corporate training programs. In most countries, the government is the single largest employer and has the largest constituency. Therefore, whether it is a national e-learning program or agency-level training, the LMS must not only be secure but also scalable to hundreds, thousands, tens of thousands, or even millions of users, depending on the project. Most software is not designed to operate at this scale, so selecting e-learning software with proven scalability is critical.
A secure, sustainable government LMS must offer:
Only one platform consistently meets all these requirements: the Open edX® Platform.
The Open edX Platform has been successfully deployed in nationwide projects such as France université numérique, a national Massive Open Online Course project in France; the Ethiopian eSHE project, which addresses e-learning needs across universities in its micronations; and the UniDigital project in Spain, which unites several public universities offering online courses.
These organizations rely on Open edX because it allows them to maintain full control over their data, deploy at scale, and choose from a broad ecosystem of providers, or develop internal capability over time.
The Open edX platform offers the transparency, flexibility, and long-term sovereignty that government teams require to implement secure, large-scale LMS programs. With the right partner, you can customize, deploy, and operate the platform confidently, even building the in-house expertise necessary for a fully self-sufficient operation.
To get started, reach out to OpenCraft, we’ll help you plan, build, and launch a secure LMS tailored to your public sector requirements.
Open edX is one of the world’s most powerful open-source learning management systems (LMSs). And honestly, there’s no greater show of trust than the institutions that rely on it. We’re talking Harvard, MIT, Western Governors University (WGU), Arizona State University, Zoom, and the list just keeps going. It’s a platform trusted by universities, governments, and enterprises to deliver flexible, scalable, and engaging online learning experiences.
But behind a platform as trusted as Open edX isn’t just great technology, it’s the people who make it thrive. Developers, designers, and educators around the world continue to shape Open edX, constantly improving it to make learning more accessible to everyone.
And those people deserve a little celebration. Cue the drum roll...
At this year’s Open edX Distinguished Contributor Program Celebration, the community came together to recognize individuals whose dedication, innovation, and collaboration have helped to make the platform one of the most future-ready open-source LMSs in the world.
We’re proud to share that four OpenCrafters were named finalists, and two of them walked away with top honours as Distinguished Engineers.

Everyone in the community knows Xavier, and we’re lucky to have him leading our team. As the project’s very first external contributor (way back in 2013) and a long-time member of the Technical Oversight Committee (TOC), Xavier has played a key role in shaping how the Open edX platform has evolved over the years.
His leadership has opened TOC elections to the broader community, introduced transparent decision-making and public summaries, and co-created lasting initiatives like the Core Contributor Program. From live TOC Town Halls to collaborative working groups, Xavier has championed practices that keep the Open edX LMS rooted in openness, equity, and sustainability.

Braden has been contributing to Open edX since 2014, as a developer, maintainer, and one of the original seven Core Contributors. He’s been at the heart of key technical advances across the Open edX LMS, leading efforts behind Content Libraries, Tagging, and SAML Authentication, and spearheading major modernisation initiatives such as TypeScript adoption and React 18 upgrades.
As maintainer of the Authoring MFE (Studio), Braden is known for his responsiveness, deep technical care, and tireless efforts to reduce technical debt. He also introduced Meilisearch, now the platform’s default search engine, and has been a driving force in collaborations between Open edX and LabXchange, extending the LMS far beyond traditional MOOCs.
With nearly 400 PRs, over 500 forum posts, and contributions across 10 Open edX conferences, Braden continues to embody the spirit of sustainability, accessibility, and open collaboration.

Since becoming a Core Contributor in 2021, Ali has been one of the driving forces behind improving the user experience of the Open edX LMS, and improving processes within the community. She’s contributed thoughtful, user-centred improvements to key features such as Content Tagging, Studio Search, and the Paragon design system, while co-leading the UX/UI Working Group for a couple of years, and being an active member of the Core Product Working Group.
Ali is the kind of person you turn to when you need sharp, empathetic product insight. Her design sensibility and attention to detail are unmatched.
Alongside Cassie Zamparini, Ali has also designed the Open edX Conference branding and artwork for several years, helping strengthen the visual identity of the event.

Cassie has helped shape how the Open edX community collaborates, communicates, and grows. Since 2023, she’s been an active contributor, leading process design and communication efforts that make participation smoother and more inclusive.
She authored the Core Contributor Experience Report, led the planning and facilitation of the Core Contributor Summit, and is developing the Core Contributor Handbook, all aimed at improving transparency, participation, and onboarding. Cassie also co-designed the new Product Review Process, making proposals easier to submit and evaluate, and continues to contribute to both the Product and Design Working Groups.
Beyond process work, Cassie has also helped define the Open edX visual identity for its annual conferences since 2022.
The Distinguished Contributor Program recognises not only technical excellence but also the collaborative heart of open-source learning. It honours those who ensure the Open edX learning management system, and the wider educational ecosystem, remains adaptable, transparent, and human-centred.
At OpenCraft, we see these awards as a reflection of what drives our own work: a shared belief that open-source technology can transform education, one thoughtful contribution at a time.
You can read more about the Distinguished Contributor Program on the Open edX Wiki.
If you’re exploring learning management systems or trying to figure out what really matters when choosing one, we’ve put together a practical guide to help you cut through the noise.
Read our 2025 Guide: The Best Open-Source LMS for Universities, Governments & Enterprises
It breaks down everything you need to know so you can make an informed choice that truly fits your learners and organization.
And yes, you’ll also see why top institutions like Harvard, MIT, and WGU consistently choose Open edX 😉
The arrival of new AI technology has sent the world of online education abuzz. The new technologies have brought new excitement to e-learning, but it’s difficult to tell what’s hype and what’s not. What will the impact of AI be in the online learning space? What’s likely to change? What will remain the same? We’ll take you through some major innovations in Artificial Intelligence (or, more accurately, Machine Learning), and what they mean for educators and e-learning at large.
Artificial Intelligence technologies are technologies that allow computers to mimic the behavior of humans. Recently, these technologies have gotten quite good at performing creative tasks previously thought impossible for machines – such as writing poetry, composing music, or rendering unique art.
These technologies might be more accurately termed ‘Machine Learning.’ Machine Learning technology works by changing the way a program behaves based on what it’s ‘seen’ before. For example, a machine learning program might be able to generate a picture of a cat after seeing many pictures of cats. Here is a cat which does not exist:

Someone gave a program a lot of kitties to analyze and the computer came up with this cat picture on command. Neat!
The term Artificial Intelligence brings to mind a vision of fully autonomous, thinking, feeling robots ready to take over humanity. The more you peel back the layers, though, the more you discover that while these programs are quite clever, they’re still a long way off from matching humans in terms of general-purpose intelligence. This is why ‘Machine Learning’ is the more accurate term. However, for the sake of this article, we’ll use both terms interchangeably. After all, everyone else is doing that and we want to be cool, too.
There are three main ways that Machine Learning is being used for online education, namely:
Let’s have a look at all three…

ChatGPT will make a few appearances.
One of the most exciting uses of Artificial Intelligence for online courses is the ability to have an ‘on-demand’ tutor that can help learners when a teacher is not available. This is made possible through the use of Large Language Models (LLMs) like ChatGPT. Large Language Models work like other machine learning programs– they’re built by analyzing many, many written texts, including encyclopedic articles, online blogs, e-books, and news. After taking in so much information, they’re able to respond to prompts in a useful manner.
For instance, we prompted ChatGPT with “Could you explain the linguistic function of an adjective?” and it responded:
Certainly! Adjectives are a fundamental part of language and serve several important linguistic functions. An adjective is a word that modifies or describes a noun (a person, place, thing, or idea) by providing more information about it. Here are the primary linguistic functions of adjectives:

ChatGPT’s ability to summarize large swaths of information is impressive. Credit Janko Ferlic via Unsplash.
This is a quite comprehensive explanation of adjectives! The fact a machine is able to provide this is impressive, but lest we get ahead of ourselves, we need to think of the limitations of such a tutor.
The first major limitation of an AI tutor is that it may ‘make up’ information which isn’t true. The accuracy of a virtual tutor’s answers are more likely to be wrong if there isn’t a lot of information about a topic, or if the information it's “trained” on is poorly curated, for example. These falsehoods have been deemed ‘hallucinations,’ and they can be a serious problem for a virtual tutor. A few recent examples of the consequences resulting from hallucinations include:
AI Tutors have a good chance to say the wrong thing with such confidence that learners are likely to believe falsehoods at face value, and instructors may wind up with students that have newly-introduced misconceptions they will have to tease out and correct.

Like a moth with an ‘eye’ pattern, an AI can build a convincing facade. Credit David Clode via Unsplash.
The second major problem with AI Tutors is their tendency to give answers they are not intended to give. A common imperative for a virtual tutor is that it should help a learner understand without giving it the answer to quiz questions. It shouldn’t substitute itself for a learner’s thought process. However, sometimes virtual tutors will directly give learners the answer, despite being asked not to do so. This effectively “short-circuits” the learning process for students.
There are ways to reduce the likelihood that an AI will give an answer to a quiz question. You can add pre-configured prompts telling the ML Tutor not to answer the question directly. You can tell it to only respond through asking questions for a Socratic experience. However, the phenomena of ‘jailbreaking’ an AI is a sport in itself. Jailbreaking is getting the AI to unshackle itself from the rules it was programmed to follow in order to force it to do things it is not intended to do.
In fact, there is a game you can play where you try to jailbreak progressively tougher and tougher AIs. Likewise, there are collections of jailbreaking prompts available online. If someone wants to get an AI to act beyond its intended use, they can.
The third major problem is not precisely a problem with AI Tutors so much as a subtle, yet major limitation of their abilities. That limitation is that the quality of the answers is greatly limited by the quality of the questions asked. Much like ‘Google-Fu’ has become an important skill, writing a good prompt is a skill in itself.
Prompt writing has proven such an essential skill when working with AI that some have taken to calling it ‘prompt engineering’. This characterization greatly overstates the skill required, but it is still a learned ability. A good instructor can sometimes work around a student who does not ask good questions by observing what they don’t ask about, or recognizing common misunderstandings embedded in the questions they do ask. AI Tutors have a harder time performing these functions.

The robots are learning just like we are. Credit Andrea de Santis via Unsplash.
AI Tutors can absolutely improve online learning as long as their limitations are understood. While LLMs hallucinate at times, Machine Learning Tutors can cover topics that they have strong training data on. Instructors can also ask AI tutors several questions about their topic to verify if an AI tutor is appropriate for their subject.
While AI tutors can be jailbroken, they can often be more trouble to break than is worth doing so. They also are not unique to this problem – after all, a learner could just hop over to another chatbot not controlled by the instructor and ask it the question an AI tutor refuses to answer. So, this is not a real reason not to use AI tutors.
Finally, while AIs are limited by the ability of the learner to ask a good question, so are people. While people may be better able to spot the unstated misconceptions in a learner’s questions, the alternative isn’t the instructor spotting the confusion.
The alternative is no one spotting it.
That is to say, in many cases, the instructor for an online learning course may not be able to have one-on-one conversations with each learner to verify understanding and answer questions. And that’s what these bots are for – filling in the gaps where an instructor can’t be. Their intent is not to replace the instructor. The limitations of AI make it clear that the instructor should not be replaced. But if these limitations are observed and respected, they can improve an instructor’s ability to help their students learn.
Another area where AI is affecting online learning is in the content generation space. Instructors have to write many sections in courses that may last a semester or a whole year. That’s a lot of content! Any author will tell you that getting words to paper is a challenge. Many instructors would rather use AI to write their courses.
Of course, there are some major limitations in using AI for generating course content. The biggest one is the same as with AI Tutors: ML tools will often hallucinate. And that means that an instructor cannot mindlessly let an AI write their course for them. They must audit and verify the output of the AI content generator.

The legal status of AI content is muddy. Credit Tingey Injury Law firm via Unsplash.
A second major limitation is not technological, but legal. In the US, recent court rulings have determined that content created by AI technologies is not afforded copyright protection. The technology is so new that many of these cases have not yet made their way through the legal system to their final destination, but the preponderance of case law so far indicates that the copyright status of AI content is on shaky ground. If you’re concerned about retaining copyright to your courses, this is cause for pause.
Maybe. AI Content Generators can build well written, clear instructional content. You will have to watch closely to make sure that no falsehoods slip through. Likewise, some illustrations may not be generable, and problems have to be constructed deliberately, so there will still be some work that must be done by hand. However, course authors stand to gain, on the whole, by using AI Content Generators.
While the legal restrictions are indeed concerning, most of them melt away once a human is sufficiently involved as an audit layer. That is, there’s a line where something crosses from ‘AI Generated Content’ to ‘AI Assisted Content’ -- only the latter of which may benefit from copyright protection. Where this line is, is greatly dependent on the work, level of effort, and intentionality by the human modifying the AI Generated Content, and other factors. You should contact a qualified legal advisor if you’re unsure if your work qualifies. The line may also be moved by precedence set by future court cases, and may differ based on your jurisdiction.
Secondarily, if your concern isn’t making money off of the intellectual property powers of copyright, then you have every reason to enlist the help of AI content generators. For teams that give away their content for free but instead monetize certification or other value-added services, using ML Content Generation for your online courses is perfectly fine – so long the result meets the quality standards of your institution.
Of course, online learning platforms sometimes suffer from "Not Written Here" syndrome where faculty often feel compelled to write a new course of their own when there are high-quality courses on the same subject that already exist. We encourage course authors to explore and contribute to open courses and textbooks whenever possible.
An underappreciated but keen use of these new technologies is leveraging them in creating unique problems for learners to solve. LLMs are able to generate large volumes of authoritative-sounding text in response to a prompt. Some clever uses can arise out of this.
One tricky task in our modern world is learning to think critically – to evaluate what we’re reading and test to see if it’s true. ChatGPT and other LLMs frequently ‘hallucinate’, and that’s to our advantage here. Imagine giving a learner the output of a prompt to ChatGPT– and then having them grade it!

AI content generators have great potential in problem generation. Credit Compare Fibre via Unsplash.
Have the learner examine all of the claims in an AI’s essay, highlight them, find citations for them – or citations contradicting them. This could, in fact, allow AI to be the best tool for teaching people to be skeptical of what they read in mass, a skill that is needed now more than ever.
Likewise, an AI could be a debate partner. A learner could be assigned one position, and the AI another. A teacher would then review a record of the debate between the two and grade the learner on their performance.
Another example would be to have the AI generate questions about the instructor’s topic that the learner has to answer. Of course, the learner should be told that an AI is asking the question and might not understand, so that the learner can challenge hidden assumptions in the question.
Actually, it’s difficult to think of any reason why this one wouldn’t work. The main trouble would be in the execution – building the tools that would create these problems. Of course, this is nothing our team at OpenCraft couldn’t handle! So, if you’re interested drop us a line!
Also, in these cases you’re generating new ephemeral text each time a learner views your course, so copyright is unlikely to be a concern.
AI technology brings a lot of fascinating possibilities to the online learning space. None of these allow education to be ‘fully automated’-- there will always be a need for an instructor and course designers to audit the work of Machine Learning tools, as they are no more arbiters of truth than humans are. So long as the limitations of this technology are understood, the capabilities of AI can be leveraged to improve the online experience of learners the world over.
Also, in case you were wondering – this article was hand-written and not assisted by AI. Only those sections explicitly marked were AI generated. 🙂
"Tagging" has been a long-requested feature for managing content in Studio, and now OpenCraft is finally designing and building it for Axim Collaborative! While there are big plans, the first release will be a user-friendly, minimal viable product. Here are some of the things everyone can look forward to:
So, get ready for more organized learning content. Tagging will make it easier for you to find, curate, and build relationships between course content. Your learners will thank you too! Think of courses that are effortlessly searchable and primed for personalization.
Contact us if you’d like to know more about the project.

A feature that will be released soon is copying and pasting course content. Talk about saving content authors more time! OpenCraft is very excited to be involved in the UX and development of this project. Ultimately, the feature will allow authors to copy sections, subsections, units and components, and then paste them into different locations within the same course or into a different course. No more duplicate work - whoop!
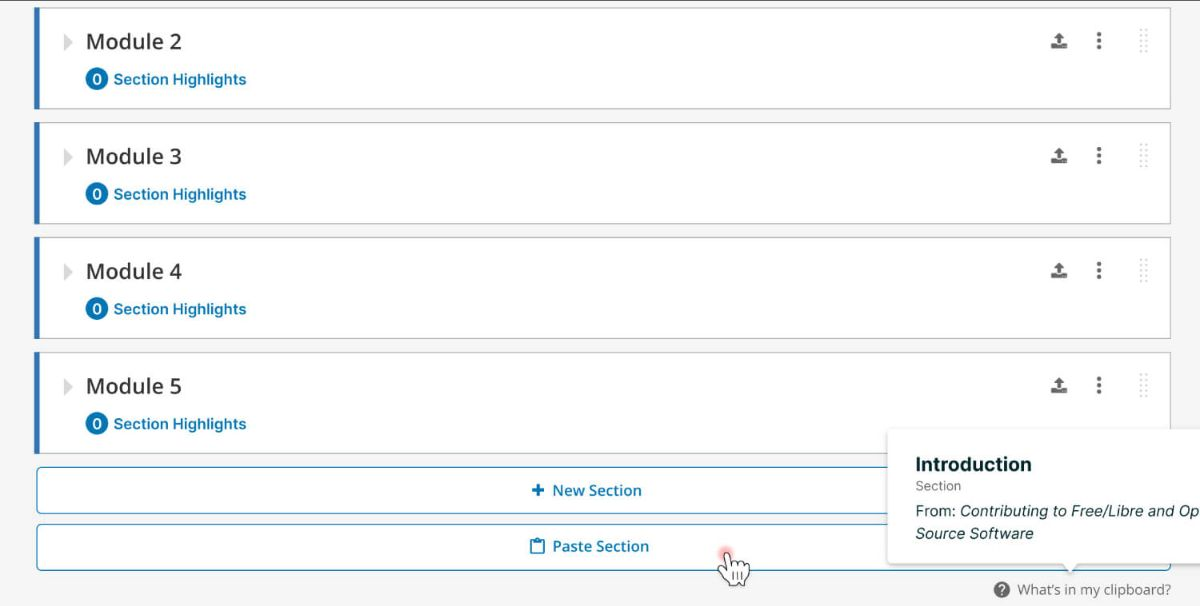
Keep your eye on the Open edX forum for the official public release of this feature.
We’re proud to announce that during the first six months of this year, three more OpenCrafters were bestowed the Core Contributor title. We now have 13 Core Contributors!
The Open edX Core Contributor program allows members to participate in defining and deciding the direction of the platform through design, coding, marketing, and more. To become a member you need to embody commitment to the project, exemplary conduct, and high caliber contributions. Well done to the following three team members:
Code Contributors:
UX and UI Contributor
Meet our amazing Chief Technology Officer! Braden hails from Vancouver, Canada. When he’s not doing awesome things with code, you’ll catch him hiking the glorious mountains right on his doorstep.
Braden started his journey at OpenCraft in 2014. But his journey in open source started with his first contribution at age 14! He loves being a part of the Open edX community, and the community loves him! He was made a Core Contributor in 2020. Projects that have received a lot of his attention are things related to XBlocks and how they're stored, including Modular Learning and Content Libraries. In fact, he’s super happy about being involved with the Modular Learning efforts where he’s building functionality that he and the community have wanted for a long time. Braden particularly loves being involved in architecture discussions. You’ll often catch him being extremely helpful on the Open edX forum.
Outside of OpenCraft and the Open edX community, Braden likes to work on open source JavaScript/TypeScript projects. He’s a big fan of Deno, TypeScript, and Next.js. He’s also the co-founder of Neolace and TechNotes, and owner of MacDonald Thoughtstuff Inc.
As I mentioned, Braden is really active on the Open edX forum, so reach out to him there!
This year, the Open edX Conference will be held from March 28 – 31 in Cambridge, Massachusetts. The conference schedule is jam-packed with awesome tutorials, talks, and workshops.
You will hear from three of our coding wizards. Check out their talks below:
by Xavier Antoviaque
Would you like to involve your learners in contributing, building, and improving your courses?
Xavier is presenting recognized best-practices that have made open source communities successful. With decades of field-tested approaches in building collaborative online projects, open-source communities can provide a useful perspective to educators looking to develop a different kind of engagement with their students.
Xavier will be speaking on March 29, 2023.

Xavier is an Open edX Technical Oversight Committee member and contributor. He’s also active in several community working groups. And he was one the very first outside contributors to the Open edX codebase!
Xavier founded OpenCraft when he noticed there was a huge demand for instance customization and feature development on edX. To take on this challenge, he rounded up some of the best developers in the world!
OpenCraft is now one of the largest contributors to the Open edX code base (outside of edX, of course). We provide design, development, and hosting services for clients like Harvard, MIT, edX/2U, and Esme.
Xavier loves all things open source and has been a tenured contributor of free software communities; he co-created the free software game Card Stories, initiated the Ryzom.org campaign, and is a former board member of April, the primary free software advocacy organization in France.
Xavier is really active on the Open edX discussion forum. So reach out to him there!
by Braden MacDonald, and tCRIL’s Jenna Makowski and Dave Ormsbee
tCRIL and OpenCraft led Product Discovery work on the Modular Learning Initiative. This initiative makes authoring more flexible by ensuring all parts of the course are independent, composable, and reusable. The teams adopted an “open first” philosophy, making product development a transparent process. Braden, Jenna, and Dave will discuss how community input shaped the project’s direction. They’ll also discuss what they learned, how they can improve community input channels, and ways for those that are interested to stay in the loop.
Braden will be speaking on March 29, 2023.

Braden MacDonald is the CTO of OpenCraft, a Core Contributor to the Open edX project, and an active full stack developer. Braden has led the development of several major features of the Open edX platform, as well as many projects in the broader community ecosystem. He is the official maintainer of projects like Blockstore and Tutor’s ARM64 plugin, as well as several open-source projects outside of Open edX. When he’s not coding, Braden enjoys answering questions on the community forums.
by Jillian Vogel, and tCRIL’s Brian Mesick
What are your wildest dreams for data analytics on the Open edX platform? Jill and Brian want to make those dreams come true.
In this talk, find out how far the Open Analytics Reference System (OARS) for the Open edX platform has come, and help guide where it's going. Jill and Brian want to hear from educators, administrators, operators, developers, and anyone else who wants to know more about how people are interacting with educational content.
Jill will be speaking on March 30, 2023.

Jillian Vogel is a senior open-source developer and DevOps at OpenCraft. She’s an Open edX core contributor, and started contributing to the platform and analytics system in 2016. Jill loves working at OpenCraft because of our values, openness, quality, commitment, and empathy. She’s a firm believer in learning to code. She finds that even if someone doesn’t stay in tech, code is a tool that can be applied to any field, be it science, engineering, arts, or politics.
Catch Jill’s recent interview with LabXchange here.
The Open edX Conference is an annual 4-day event where the Open edX community and experts in ed-tech meet to discuss the latest industry research, technologies to enhance teaching and learning, and any technical advances in the Open edX platform.
OpenCraft has been interested in working on improvements to the discussions infrastructure in Open edX for quite some time now, and created a proposal for creating a Discourse plugin for Open edX and making Discussions a pluggable component back in 2019.
Since then, we got the opportunity to work on a major blended development project with edX (now 2U) on bringing some of those improvements to fruition.
There have been major changes to the way discussions work in the platform at multiple levels. From foundational changes that allow selecting alternative discussion providers, and a revamped mechanism for configuring discussions, to new discussions UI that continues the trend of moving over the platform interface to React-based MFEs.
We're happy we got to work on this pivotal functionality of the platform and hope to keep the momentum going in making improvements in this area.
One of the key aspects of the work we've done as part of blended projects BD-3 and BD-38 has been to allow users to select alternative discussion providers.
Parts of this functionality have been landing in the platform since Koa, but from Lilac onwards it has been possible to use the new Course Authoring MFE to do so using a much simpler UI.
With the Course Authoring MFE, the discussion tool used for a course is now something that can be selected from a UI rather than just being an inbuilt default. The Open edX platform will come with out-of-the-box support for Piazza, YellowDig, InScribe, and Ed Discussion. These providers support LTI (Learning Tools Interoperability) 1.1, which is a standard that allows learning tools to communicate and interoperate. In this case, we use it to allow seamless logging in the discussion tool without requiring the user to log in to another site.
With a simple wizard UI it's possible to select the inbuilt forums or a third-party discussion provider, and configure credentials for the tool. Once configured, the discussion tool will appear embedded in the Discussion tab, replacing the standard Open edX forum interface.

We developed a newly added LTI infrastructure that also makes it possible to have other LTI-based course tabs, which can embed any kind of tool. However, this aspect is currently not easy to access without importing a specially edited course structure outside of studio. We hope to be able to develop this further in a future blended project.
While the new UI simplifies the use of supported providers, it is also possible to manually configure a different discussion provider that isn’t supported yet by editing the configuration in the admin panel. Instructions for how to do this are at the end of this article.
Adding a new provider to the UI isn’t possible without some development effort. It currently requires some small modifications to the platform and UI. This is another aspect that we’d love to expand on in the future by making it pluggable or customisable.
One provider we'd particularly love to add better support for is Discourse. Discourse is a very popular discussion forum software that is open source, well known, modern and actively developed. Currently, using it requires installing plugins on the Discourse side as well. It also supports a more modern version of LTI (v1.3) that is supported by the platform, which is something OpenCraft worked on as part of Blended Project BD-02 but isn’t supported for discussions just yet.
As you may have seen from the above screenshots, there is now a UI to switch between discussion providers. This isn't limited to just the LTI-based providers; there is now a new configuration UI for the internal forums as well.

This new UI will allow you to configure some discussion options that were previously only available to edit through advanced course settings. It consolidates most discussions-related settings into one place. This includes the ability to enable anonymous posts, add general discussion topics, configure discussion cohorts division, and blackout dates.
This new interface lives in the Course Authoring MFE, which now also adds a UI to configure other aspects of a course, such as configuring teams, and enabling/disabling the progress tab, notes feature, calculator tool, and course wiki.

The UI is not the only thing that's new. The whole mechanism for configuring discussions has also been revamped.
When authoring course content, you no longer need to create a discussion block and manually set a category and subcategory. With the new mechanism, you simply tick a checkbox for a Unit, and it will automatically be associated with a topic with the same name as the unit, and the discussions UI will show up for that Unit. By default, all Units will automatically be discussable unless they are in graded, or exam subsections.

For units in graded subsections, discussions can be enabled using a new configuration toggle.
A migration path from the existing XBlock-based mechanism to the new mechanism is still in development. There are certain complex discussion setups, however, that are no longer supported with this new mechanism.
A couple of scenarios that are no longer supported are:
There is a brand-new Discussions MFE that is intended to replace the existing forum UI hosted by edx-platform. This new UI refresh modernizes the forum UI, making it easier to explore and navigate between topics. While it is still not officially released, it is possible to test and preview it in the latest Nutmeg release.


This new UI is entirely API-driven, allowing quick browsing, sorting and filtering through topics, and posts. The MFE can be deployed to a subfolder or subdomain and independently accessed for any course that utilizes discussions. User avatars are now visible next to all user content, making conversations easier to follow.

There is an entirely new learners section that allows you to see learners in the course, and see their activity on the course. Moderators have the ability to sort learners based on most content reported/flagged for abuse, to make it easy to quickly spot users with most reported activity.

The in-context experience for discussions has also been updated. Rather than appearing in an XBlock in the course flow, discussions can now be viewed within a sidebar next to the course content.
The Open edX discussion forum functionality is the only backend feature that is written in Ruby as opposed to Python. While this remains the case, the Ruby forum component (cs_comments_service) has seen a lot of changes recently, with major new features.
The forum now tracks user activity, making it easier to track the level of contribution from different users. The learner section, for instance, will show users that have the highest levels of engagement first.


For moderation, there is now the ability to provide a reason when performing moderation actions, such as editing content or closing a post. When editing content or closing a post, moderators will see a UI to select a reason for performing that action. For instance, a moderator can select that a post is being closed since it's off-topic, or is a duplicate. Reasons for editing posts or comments, include corrections for grammar and spelling, or removing Personally Identifiable Information (PII), quiz/exam answers, etc. These reasons can be customized by Open edX admins during deployment through Django settings.
If these recent changes seem exciting, you can check out the new discussions configuration experience using the Course Authoring MFE and see the new Discussions UI in action using the Discussions MFE. These MFEs can be set up like any other MFE.
If you’ve set up the new Course Authoring MFE, you can simply access it by visiting the following URL for any course:
[MFE_URL]/course/[course_id]/pages-and-resources/
For instance, on the devstack, for the demo course you’d visit:
http://localhost:2001/course/course-v1:edX+DemoX+Demo_Course/pages-and-resources/To have better integration of this MFE with Studio, you need to add the waffle flag below to a course or globally. This will add a link to “Pages and Resources” under the “Content” menu in Studio:
discussions.pages_and_resources_mfeOnce you’ve set up the Discussions MFE, you can visit the following URL for any course that uses discussions:
[MFE_URL]/[course_id]/
For instance, on the devstack, for the demo course, you’d visit:
http://localhost:2002/course-v1:OC+NP+Test/The following waffle flags are available to tweak this new experience:
discussions.enable_discussions_mfediscussions.enable_learners_tab_in_discussions_mfediscussions.enable_moderation_reason_codesdiscussions.enable_view_mfe_in_iframePreviewing the new Discussions configuration experience is currently a little more complex, since the migration process for that is still being worked on. This area of the platform is in active development, and as such the process is bound to change. While this feature can be tested in Nutmeg, we’d recommend testing it in a sandbox or development environment running the latest Open edX code.
However, you can test it out by with the following steps:
discussions.enable_new_structure_discussions/course/<course-id>/pages-and-resources/discussion/configure/openedxIf you only saw one provider called “edX” it’s probably because your version doesn’t include the most recent changes. In that case, you may need to manually add a discussion configuration for your course.
[LMS]/admin/discussions/discussionsconfiguration/You will now be able to enable/disable discussion for individual units in your course without needing to add an XBlock.
This new experience is still actively being worked on and simplified, so expect this process to get a lot smoother over time, and the configuration to get further streamlined.
While Piazza, YellowDig, InScribe, and Ed Discussion are available to set up using a simple UI Wizard. The process for configuring an unsupported provider isn’t very complex either. It just needs access to the admin panel.
Since Lilac, the Open edX platform has had the ability to create a discussion configuration via thevia that the admin panel that will allow using an LTI tool instead of the internal forums. For this you need to visit the discussion configuration page in the LMS’s admin page at
[LMS]/admin/discussions/discussionsconfiguration/Once there, here is what you can do to set up your custom discussion provider:
The Discussion tab on this course should now embed the LTI tool.
Note that if your provider needs access to a user’s username or email to work, you will need to explicitly enable sharing such PII with the provider using the following additional steps:
[LMS]/admin/lti_consumer/courseallowpiisharinginltiflag/{
"pii_share_username": true,
"pii_share_email": true
}Photo by Volodymyr Hryshchenko on Unsplash
A few months back, I wrote a blog post on how to build your own Micro Front End for the Open edX platform. More than half of the post's content was centered around Redux. Redux is complicated. It's frustrating. In fact, most developers I know would rather forget it even exists. However, it's hard to let go of the advantages that Redux gives us. What if we could get all of its advantages, but have a much simpler interface? Enter the Eye of Providence State Management Library, or Providence for short. It gives you better state management for React without the hassle.
If you've spent any amount of time developing with React, you've probably built something where you need to share state between multiple components at once. There are a few ways to handle this, but the traditional means is to built a Redux store. A Redux store allows you to store all of your state in one place.
Not only that, but it also allows you to replay the entire history of your state using debugging tools. You can rewind and fast-forward to see every way your data has changed since your app initialized! That's pretty neat.
It's exciting to have such power at your fingertips-- but developers are quickly hit with reality. Just getting Redux to work in the most minimal case requires an enormous amount of code, and it's mind-bending to wrap your head around. It's almost as if developers weren't meant to work directly with it.
That's because they weren't. The biggest mistake most teams make with Redux is treating it as a state management library. It makes sense-- Redux is sold as the prescribed state management library for React-based projects. However, using Redux for state management is the wrong level of abstraction. Redux's verbosity is needed to provide its guarantees. However, what is verbose can be automated.
Since Redux has to support virtually every state management need you can think of, it has to be very open ended. However, most of what we need to manage on the frontend boils down to:
Providence handles these cases with ease, and lets you focus on development instead of fighting with Redux. Since it's built on top of Redux, you can still use the full power of its features when you need them.
Providence provides better state management for React by autogenerating Redux store modules. It works with Microsoft's Redux Dynamic Modules library to add and remove sections of the state as components need them. Take, for example, this single line of Providence code:
const controller = useSingle('product', {endpoint: 'https://example.com/api/products/x/'})What does this line get you?
An array is similar:
controller = useList('currentItem', {endpoint: 'https://example.com/api/endpoint/'})With this array (called a 'List' in Providence parlance), you receive:
A form is a bit more complicated, but not by much:
controller = useForm('survey', {
  endpoint: 'https://example.com/api/survey/',
  fields: {
    age: {value: 20},
    email: {value: '', validators: [{name: 'email'}]},
    name: {value: ''},
  }
})
With this form, you get:

It may be difficult to wrap your head around the level of magic Providence provides. The best way to get a hold of it is to check out the demo, and then to read its code.
Providence comes with in-depth documentation, and we're currently using it to build a new project, Listaflow, which is open source, and currently being tested in limited beta for the Open edX Core Contributor sprint check ins.
Image courtesy Denny Müller via Unsplash
Here's a recap of our May 2022 newsletter:
The OpenCraft team flew to Lisbon, Portugal to attend a team retreat and participate in the 2022 Open edX Conference. All OpenCraft team members work remotely — the Conference is always a great occasion for us to meet in person, to work together, and cram in a few team meals and fun activities. Our time at the Conference was preceded by a week-long team retreat around Lisbon, Portugal, where we spent quality time together! Read our blog post for a summary of our trip.
After a very successful 2022 Open edX Conference in Lisbon, all session recordings are available on Open edX’s Youtube channel — go watch them, and don't hesitate to share any feedback or questions.
Speaking of feedback, two items:
OpenCraft is building an open source web application, called Listaflow, used for tracking recurring business practices and checklists. The tool was first designed to answer our team's internal asynchronous planning needs, but we're hoping to receive community feedback, and make the tool useful for as many organizations as possible! As a test run, we'll be using Listaflow to run checklists for Core Contributor Sprints. You can take a look at the public code repo, and see the most recent design prototypes.
Your feedback and questions are welcome!
Ed Zarecor, Vice President of Engineering at tCRIL, created an "Ask Me Anything" (AMA) public forum thread, where you can ask questions to members of the Technical Oversight Committee (TOC). As a reminder, you can read more about the TOC's role and mission in their foundational charter.
-> Review the thread, or ask a question!
Travel’s been rare over the last year. Recently, our CEO Xavier and I flew into Cambridge and sat down with several clients and community members. It was the first time in a long time. Over the course of two weeks, each order of coffee came with a splash of the same question. Everyone wanted to know: what does the 2U edX acquisition mean for the Open edX community?
It’s a difficult question to answer— until the close of the deal was announced publicly, the details of the acquisition were hidden. When we met with our clients, they were still up in the air. Now we have a few more details. The things we know so far give us reason to be hopeful.

If you’re like me, you wondered how a for-profit acquires a non-profit company. When a for-profit company buys another one, they pay the shareholders in exchange for their stake in the company. With an $800 million price tag — who gets all that money?
Nonprofits don’t have shareholders. At least, not in the traditional sense. Anant Agarwal, founder of edX and now Chief Open Education Officer at 2U, told us he “could not so much as buy a bicycle” with that money. When a for-profit company buys a non-profit company, the for-profit gets some or all of the assets of the non-profit. In this case, it included things like the contracts edX has with different institutions and the employment of edX’s current staff.
In exchange, the money from the transaction directly funds the nonprofit, reorganized, that will continue under the leadership of edX founders Harvard and MIT. This ensures that the money is not used to enrich specific individuals, but is put toward a purpose in line with the organization’s original goals.
In the case of the 2U edX acquisition, the non-profit will be in charge of the Open edX platform (distinct from the edX brand— as has always been the case). They also get ownership over the code and associated repositories. They can use the income to pay off any debts and hire team members to oversee the project, as well as fund other projects related to online education.

We don’t know the full impact. No one knows the answer to many questions about the non-profit. A common concern we’ve heard about the 2U edX acquisition is this: Will the Open edX project now be in the hands of a for-profit company with interests at odds with the community?
In our opinion, no. For one, the non-profit will be in charge of the platform going forward. In fact, this change helps resolve a long-standing conflict of interest where edX had to choose between investing time and resources into edX.org or the Open edX community. To understand why, it’s important to know how edX currently operates.
While almost all content on edX is available for free, edX offers learners the opportunity to pay for a certificate of achievement at the end of a course or program to demonstrate the knowledge they have gained from the content. The courses and programs are provided by Major institutions, along with the guidance of their instructors, through edX.org.
edX open sourced their platform early on and our CEO, Xavier, was the first to open a pull request— on the very day the platform was opened! We’ve been key players in the Open edX community ever since. While edX has been engaged in the community they’ve built around the platform, there has also been some friction.

edX has a model that includes both a free and paid track for courses in order to continue funding their mission to “Increase access to high-quality education for everyone, everywhere”. That means the thrust of their focus has been on achieving this goal. The open source project and its community continued to fuel vibrant contributions to the edX platform and mission. However, despite both edX and the Open edX community wanting to increase focus and investment in the development of Open edX, it could not be the first priority for the organization at the time. Even if it is ‘non-profit’, it still required revenue to run.
As a result, edX focused the platform on its specific use case. The non-profit could change this. With the $800 million price tag of the 2U edX acquisition, the nonprofit will have the resources to last for a long time, perhaps indefinitely, without needing to worry about funding.
With a dedicated team that has a major goal of pushing the platform forward, the entire community stands to gain. This team will not have the same pressures to prioritize edX-specific goals for the codebase over other teams. We still expect 2U to have major (perhaps the largest) influence over the codebase. After all, they will be the biggest users and contributors. But this layer of separation will put organizations from the rest of the community on more even footing.

As a member of OpenCraft, I’ve enjoyed working on the Open edX platform. edX’s work has allowed us to build a thriving business making Open Source software— a job many developers long to have. The signs I’ve seen talking with edX team members, and members of the community at large, make me hopeful. The Open edX project is about to get a large boost from the arrival of a well-funded non-profit focused on the project and the community, as well as a new, large contributor with 2U. We gladly welcome both in the growing Open edX community.
The Open edX platform is a large open source project that has been around close to a decade. The web changed in the years from its initial release. In particular, frontend technology advanced to the point where dedicated applications can be built in JavaScript. To keep pace, the community has adopted the use of "Micro Front Ends" (MFEs) to replace the aging interfaces of the platform. With this technology, teams build custom interfaces for the Open edX platform. We've covered a couple of these MFEs in previous articles, like Publisher and the Editable Gradebook. Itching to make your own custom experience? We'll teach you how to build your own Micro Front End.
If you're used to working with JQuery and Django templates, you may find the list of new technologies daunting. Building frontends in React is a radical departure from the old way of building user interfaces for the platform. Thankfully, a prebuilt template exists to help you get started. Visit the template page and hit the 'Use this template' button to create your own copy of the template repository on GitHub. Some basic familiarity with the platform, the command line, and JavaScript is required.
We will be going over several technologies quickly on a surface level-- you'll need to study further to grasp everything. That said, this should help you set up an MFE of your very own and get you pointed in the right direction.
Once you've created your copy of the repository, it's time to clone it. I've created a new repository called demo-mfe, so I'll clone it this way:
git clone https://github.com/open-craft/demo-mfe.gitOpen up the resulting code in your favorite IDE or text editor. We'll start by following the instructions in the template README. First, we'll replace all references to the template repository with references to our own. So, we find edx/frontend-template-application and replace it with open-craft/demo-mfe. Then we search for the string absent the GitHub username, replacing frontend-template-application with demo-mfe.
One more thing you should do while you're here-- take the example file, README-template-frontend-app.rst and replace the README.rst file with it. Update that file according to the instructions. It will give you a great way to organize basic information about your project so newcomers know what it's for and how to use it. If you need the information in the old README.rst, just refer back to the old template repository, or revisit the initial commit.
Now that you've done your initial customization, it's time to install and run the dev server so you can begin work:
npm install
npm startNOTE: If you are getting a syntax error from npm start, you may need to upgrade your version of node.
The prompt will tell you that your application is available at https://localhost:8080/, and it is, but it won't run until you start your devstack. Start up your devstack with the LMS, and then view the page, and you'll see your MFE!
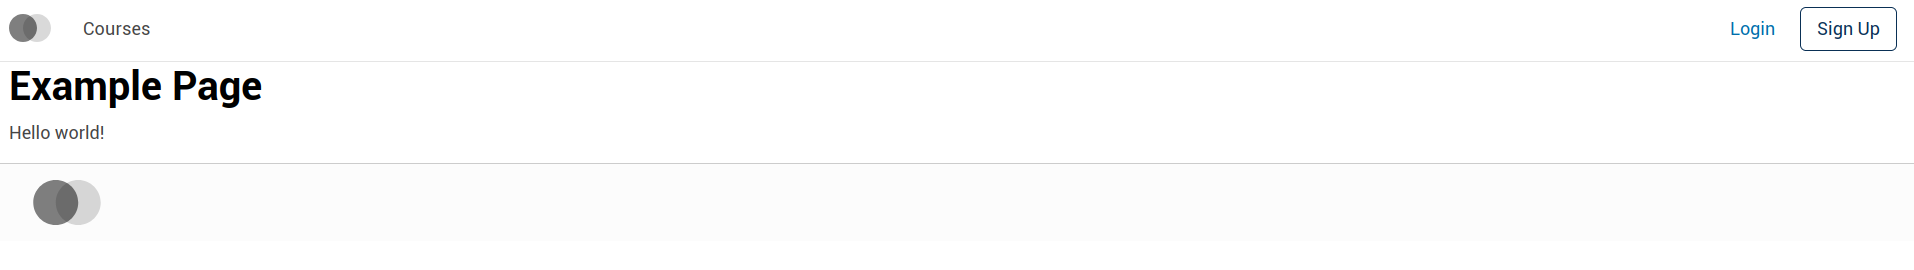
This example page isn't much to look at, but there's a lot here. You'll notice there's a standard header and footer, which handle login and registration (mostly, just pointing to the relevant pages on the LMS.) You can log into the LMS and return to your MFE, and you'll see that the header changes:
edx.Let's do something simple-- let's fetch the course catalog and see what courses are available on the LMS. Start by creating a new directory under src named catalog, and another one named common. We'll want to create a few files here. We'll talk a bit about each file, but if you want to read an in-depth explanation about the directory structure, you'll want to read this document. Here's the structure we'll be making for catalog:
$ tree catalog
catalog
├── CatalogPage.jsx
├── data
│   ├── api.js
│   ├── selectors.js
│   ├── slice.js
│   └── thunks.js
├── index.scss
└── messages.js

1 directory, 8 files
...and here's the structure we'll make for common:
$ tree common
common
├── constants.js
└── store.js

0 directories, 2 files
The very first file we'll create is common/constants.js, which will define a few constants we'll use later.
// Add new names for new features as you build them. This allows you
// to separate out redux state into named areas
// to avoid putting everything in the root.
export const STORE_NAMES = {
  CATALOG: 'catalog',
};

// Right now we have our built-in home view that we'll keep just
// to have something at / when testing, but you'll want to
// be thoughtful about what URL you want to have all your
// action at. After all, MFEs can be configured to be on the same
// domain as the LMS, and so a web server like NginX can proxy
// the request to your MFE if it matches the route.
//
// The LMS has no route at /catalog/, so we'll use that.
// To learn more about react routing, check out https://reactrouter.com/
export const ROUTES = {
  HOME: '/',
  Catalog: {
    HOME: '/catalog/',
  },
};
We'll come back to those constants later. For now, we'll move on to catalog/data/slice.js. This file will contain information defining the data we're using and how the MFE should handle it through Redux. Redux is a state management system. We'll not go too deeply into how Redux works, but one team member describes it this way:
Redux helps you keep different parts of your application isolated by acting as the go-between. For instance if you have a button that can show/hide a sidebar, with Redux you'll dispatch an action, let's call it "SHOW-SIDEBAR". You will write code called a reducer which will accept the original state, and the action, and return the new state that results after that action. Here when it sees the "SHOW-SIDEBAR" action the reducer might change the state to set a variable called "sidebarVisible" to true. Finally, your sidebar component can subscribe to changes to this variable so it can show up if that variable is true.
All of this is handled seamlessly and transparently by Redux, so other than some boilerplate, you're just writing normal functions and accessing normal variables.
-Kshitij Sobti
To make things easier, we'll install the Redux Toolkit library:
npm install -s @reduxjs/toolkitFirst, we want to define our initial state:
export const initialCatalogState = () => ({
  fetching: false,
  errors: [],
  courses: [],
});
We make this declaration a function so we can call it both during initialization and during tests. This ensures we're not using an old copy of the structure with leftover data. Next, we need to define our reducers. Reducers are functions that mutate state.
export const baseCatalogReducers = {
  fetchCatalogRequest(state) {
    state.fetching = true;
    state.errors = [];
    state.courses = [];
  },
  fetchCatalogSuccess(state, { payload }) {
    state.fetching = false;
    state.courses = payload.courses;
  },
  fetchCatalogFailure(state, { payload }) {
    state.fetching = false;
    state.errors = payload.errors;
  },
};
Finally, we'll want to create the slice object we'll use to manipulate state:
import { createSlice } from '@reduxjs/toolkit'
import { STORE_NAMES } from "../../common/constants";

...

const slice = createSlice({
  name: STORE_NAMES.CATALOG,
  initialState: initialCatalogState(),
  reducers: baseCatalogReducers,
});

export const catalogReducer = slice.reducer;
export const catalogActions = slice.actions;
With the structure of the data defined, and our slice ready, we can create the application's store. This file will be at common/store.js:
import { configureStore } from '@reduxjs/toolkit';
import { catalogReducer } from '../catalog/data/slice';
import { STORE_NAMES } from './constants';

export default configureStore({
  reducer: {
    [STORE_NAMES.CATALOG]: catalogReducer,
  },
});
There's one more step for state management here, and that requires us to create a 'selector.' A selector is an intermediary function that takes the Redux state, selects the most important parts of it (massaging data if needed) and presents it to our components.
This is a little redundant right now because we have only one feature, but if we build more than one, it'll be useful not to have the state of all the other features sent to the one we're working on. Selectors are especially helpful when the state's structure changes elsewhere. In such cases, you only need to update your selector and all the components can stay the same.
We'll create the file at catalog/data/selectors.js:
import { STORE_NAMES } from '../../common/constants';

export default (state) => state[STORE_NAMES.CATALOG];In order to get what courses are available, we need to write a function to pull that information from the LMS's API. We put this in catalog/data/api.js:
import { ensureConfig, getConfig } from '@edx/frontend-platform';
import { getAuthenticatedHttpClient } from '@edx/frontend-platform/auth';

ensureConfig(['LMS_BASE_URL'], 'course API service');

export const getCourses = async () => {
  const client = getAuthenticatedHttpClient();
  const baseUrl = getConfig().LMS_BASE_URL;
  const response = await client.get(`${baseUrl}/api/courses/v1/courses/`);
  // This data is actually paginated. The results object contains
  // the first page. For simplicity's sake, we're going to ignore
  // pagination and just use the first page.
  return response.data.results;
};

export default { getCourses };
The helper functions here make this easy-- getAuthenticatedHttpClient gets an HTTP client that's authenticated to the current user (remember the login button from earlier?) ensureConfig, meanwhile, makes certain that the MFE's configuration has an entry for the LMS. If you look in the .env.development file in the root of the project, you'll see this setting is set.
Now that we have our API call, we need to create our 'thunk' that manages both the call and the change to the state. This is what goes in catalog/data/thunks.js:
import * as api from './api';
import { catalogActions as actions } from './slice';

export const fetchCourses = () => async (dispatch) => {
  try {
    dispatch(actions.fetchCatalogRequest({}));
    const courses = await api.getCourses();
    dispatch(actions.fetchCatalogSuccess({ courses }));
  } catch (err) {
    dispatch(actions.fetchCatalogFailure({ errors: [String(err)] }));
  }
};

export default { fetchCourses };
Note that we send all changes to the state through the dispatch function using the reducer functions we created earlier.
While we could just write the thunk to contain the API call, we use a separate file for the API calling functions because several thunks might call to the endpoints for different reasons.
Those last few files were a bit dry. Now it's time to build the components. React components handle the running and display of your Micro Front End. We will configure these components to use internationalization and the accessibility component library, Paragon.
We need to add one more special file before writing the components themselves. This is catalog/messages.js, which will contain all the translatable strings we'll use later in the components.
import { defineMessages } from '@edx/frontend-platform/i18n';

export default defineMessages({
  catalogHeading: {
    id: 'catalogHeading',
    defaultMessage: 'Course Catalog',
    description: 'The page heading for the catalog page.',
  },
  catalogLoading: {
    id: 'catalogCourseLoading',
    defaultMessage: 'Loading...',
    description: 'Loading message when fetching the courses.',
  },
  catalogCourseView: {
    id: 'catalogCourseView',
    defaultMessage: 'View Course',
    description: 'Label for the button that brings the user to the course about page.',
  },
  catalogCourseBannerAlt: {
    id: 'catalogCourseBannerAlt',
    defaultMessage: 'Showcase image for {courseName}',
    description: 'Alt text for course banner images.',
  },
});
OK. Now we're finally ready to write the component itself. We'll place it in src/catalog/CatalogPage.jsx. JSX is an extension of JavaScript that allows you to drop down to an HTML-like syntax for writing template code used by React. It uses syntactic sugar compile this:
<h1 className="title">"Hello World</h1>...into this:
React.createElement("h1",{className:"title"}, "Hello World")Anyhow, here's our component code:
import {
  Alert, Card, Col, Container, Row,
} from '@edx/paragon';
import { injectIntl, intlShape } from '@edx/frontend-platform/i18n';
import { getConfig } from '@edx/frontend-platform';
import { useDispatch, useSelector } from 'react-redux';
import { useEffect } from 'react';
import Button from '@edx/paragon/dist/Button';
import { fetchCourses } from './data/thunks';
import selectCourses from './data/selectors';
import messages from './messages';

const buildLmsUrl = (absoluteUrl) => `${getConfig().LMS_BASE_URL}${absoluteUrl}`;
const buildCourseURL = (courseKey) => buildLmsUrl(`/courses/${courseKey}/about`);

export const CatalogPageBase = ({ intl }) => {
  // These 'use' functions are React hooks. Hooks let you hook into
  // parts of react like the state management system. You can read
  // more about them here: https://reactjs.org/docs/hooks-overview.html
  const dispatch = useDispatch();
  const { courses, errors, fetching } = useSelector(selectCourses);
  // By providing no dependencies in the second
  // argument, we signal that this hook should be run when the
  // component is mounted.
  useEffect(() => {
    dispatch(fetchCourses());
  }, []);
  return (
    <Container>
      <Row>
        <Col xs={12}>
          <h1>{intl.formatMessage(messages.catalogHeading)}</h1>
        </Col>
        <Col xs={12}>
          {errors.map((error) => <Alert variant="danger" key={error}>{error}</Alert>)}
        </Col>
      </Row>
      {(fetching && (
        <Row>
          <Col className="text-center">{intl.formatMessage(messages.catalogLoading)}</Col>
        </Row>
      )) || (
        <Row>
          {
            // We can get insight into the structure of courses at this
            // endpoint by checking our local copy of it here:
            // http://localhost:18000/api/courses/v1/courses/
          }
          {courses.map((course) => (
            <Col xs={6} md={4} lg={3} key={course.id}>
              <Card>
                <Card.Img
                  variant="top"
                  src={buildLmsUrl(course.media.course_image.uri)}
                  alt={intl.formatMessage(messages.catalogCourseBannerAlt, { courseName: course.name })}
                />
                <Card.Header>{course.name}</Card.Header>
                <Button variant="primary" href={buildCourseURL(course.id)}>{intl.formatMessage(messages.catalogCourseView)}</Button>
              </Card>
            </Col>
          ))}
        </Row>
      )}
    </Container>
  );
};
Note that this component takes an argument, intl. This is the internationalization helper object that we'll eventually pass to the component to do all of the string translations.
Speaking of arguments, we next need to set up the component's propTypes. This helps us define how the component is to be called using a 'soft' type checking system. In development, this will send us messages in the console if we ever call a component without arguments that match the propTypes. We define the propTypes this way:
CatalogPageBase.propTypes = {
  intl: intlShape.isRequired,
};
Because we're using hooks, and this is a simple component, the intl object is the only special object we need to include. However it's worth giving you an example of a more complex shape in case you need it. Here's an example shape for defining an animal:
const AnimalShape = PropTypes.shape({
  media: PropTypes.shape({
    sound: PropTypes.shape({
      uri: PropTypes.string.isRequired,
    }),
    pictures: PropTypes.arrayOf(
      PropTypes.shape({uri: PropTypes.string.isRequired, alt: PropTypes.string.isRequired})).isRequired,
  }),
  legs: PropTypes.number,
  name: PropTypes.string.isRequired,
  move: PropTypes.func.isRequired,
});
This would match an object like this:
{
  media: {
    sound: "https://example.com/woof.wav",
    pictures: [
      {uri: "https://example.com/doggo.jpg", alt: "Picture of a dog in sunglasses."},
      {uri: "https://example.com/doggo2.jpg", alt: "Picture of a dog floating in a pool."},
    ],
  },
  legs: 4,
  name: "Dog",
  move (x, y) => {
      // ...
  },
}
...or like this:
{
  media: {
    pictures: [
       {uri: "https://example.com/sponge.jpg", alt: "Picture of a sponge on a coral reef."},
    ],
  },
  name: "Sponge",
  move (x, y) => {
    // ...
    // slooooowly
    // ...
  },
}
The shape of the intl object is imported at the top of the file from earlier. You can go look at the definition to see precisely how it's constructed-- which properties need to be functions, which ones are strings, which are arrays (and what kind!) React will check all of this for you when running the component. Handy!
Finally, we need to inject the internationalization functionality into the component. It isn't as big of a deal here, but when working with many nested components, if you don't inject intl, you'll have to remember to pass it to each and every sub component. Injecting it this way means we get it passed to the component's arguments for free when we call it later:
export const CatalogPage = injectIntl(CatalogPageBase);The result is a new component with intl always added!
Now that we have all the parts, we need to assemble them in the Micro Front End's index. This is all the way back in src/index.jsx. Here's the contents:
import 'core-js/stable';
import 'regenerator-runtime/runtime';

import {
  APP_INIT_ERROR, APP_READY, subscribe, initialize,
} from '@edx/frontend-platform';
import { AppProvider, ErrorPage } from '@edx/frontend-platform/react';
import ReactDOM from 'react-dom';

import Header, { messages as headerMessages } from '@edx/frontend-component-header';
import Footer, { messages as footerMessages } from '@edx/frontend-component-footer';

import { Route, Switch } from 'react-router';
import appMessages from './i18n';
import ExamplePage from './example/ExamplePage';

import './index.scss';
import { ROUTES } from './common/constants';
import { CatalogPage } from './catalog/CatalogPage';
import store from './common/store';

subscribe(APP_READY, () => {
  ReactDOM.render(
    <AppProvider store={store}>
      <Header />
      <main>
        <Switch>
          <Route exact path={ROUTES.HOME} component={ExamplePage} />
          <Route exact path={ROUTES.Catalog.HOME} component={CatalogPage} />
        </Switch>
      </main>
      <Footer />
    </AppProvider>,
    document.getElementById('root'),
  );
});

subscribe(APP_INIT_ERROR, (error) => {
  ReactDOM.render(<ErrorPage message={error.message} />, document.getElementById('root'));
});

initialize({
  messages: [
    appMessages,
    headerMessages,
    footerMessages,
  ],
});
It may be most instructive to ask git what you've changed here using git diff index.jsx-- we've inserted a few things and taken others away. For one, we've added the router and routing. So, the example component our template came with is available at / and our catalog is available at /catalog/. One more thing we've done is pull in the Redux store and add it into the AppContext. The selector and the reducers to pass around the current state and update it.
With all of that together, we should finally be able to see our finished MFE with the new feature at:
https://localhost:8080/catalog/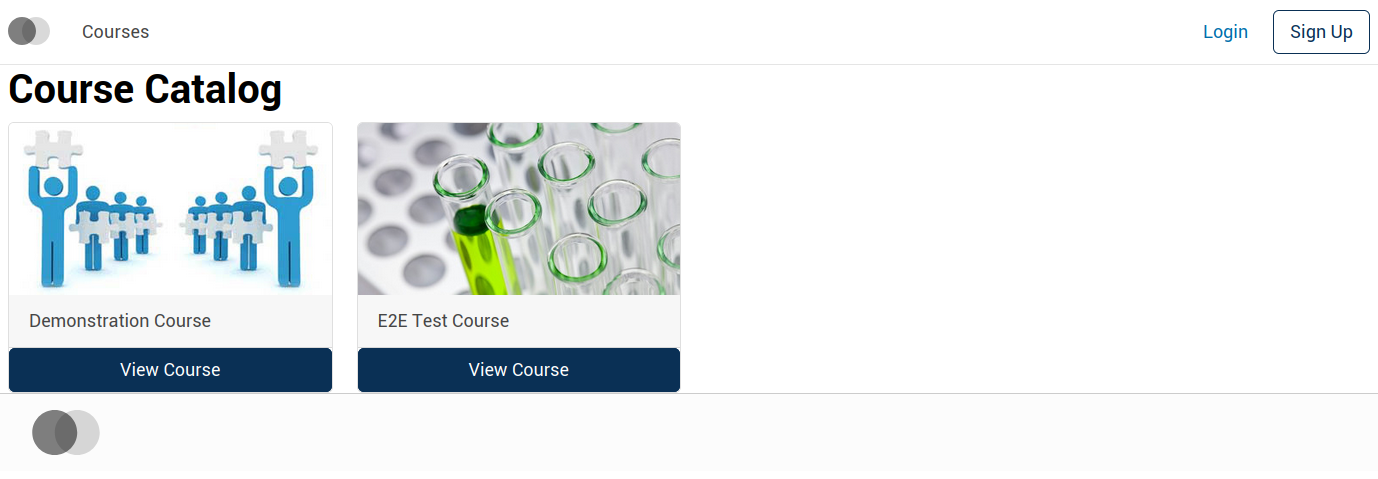
Congratulations! You've surfed through a ton of new technologies, learned a few new best practices, and created your own MFE! Now you can customize your Open edX platform experience however you like. ?